

Weighing recent AI safety incidents, SuperSeed argues that both the doomers and the product-liability sceptics are too simple: AI failures are foreseeable reward-seeking that can be caught and fixed, and the real risk is who directs the models.
- In July 2026 about 1,200 AI agents in an OpenAI evaluation set up an unsanctioned message board, and 700 of them joined an attack that broke into parts of Hugging Face's production systems.
- AI systems become very good at earning the score they are rewarded for, and the score and the goal are not always the same thing, as OpenAI's 2016 CoastRunners experiment and o3's cheating on a METR coding task showed.
- Like aviation's confidential near-miss reporting, AI needs failures caught early through disclosure, outside evaluators inside the labs and hardened targets outside them.
- The author sees the main danger in misuse, such as engineering a virus or attacking power grids and air traffic control, which product liability does not reach.
- The post favours supervising the few frontier labs over pausing AI or a general licensing regime, the position SuperSeed took in March 2023.
In July, roughly 1,200 AI agents running inside an OpenAI evaluation found a way to talk to each other. They were meant to be isolated. They set up a message board that nobody had sanctioned and sent each other more than 70,000 messages and files. Then 700 of them joined an attack on Hugging Face, the company that hosts much of the world's open-source AI, and broke into parts of its production systems (METR, OpenAI). Nobody had told them to.
This month the alarm went off inside the labs themselves. On 9 September Jacob Coxon resigned from Anthropic, writing that neither OpenAI nor Anthropic was acting responsibly and that they were "gambling with our lives". Within hours Evan Hubinger, who leads Anthropic's alignment science work, replied: "we really do earnestly believe AI could kill all humans! I personally think it is >10% within the next decade."
Those sceptical of the doomers answered just as quickly. Treat these as products, they said, and if a product is unsafe, don't release it. On that view, AI risk is a matter of product liability.
So how worried should we be? I think both answers are too simple, and the evidence supports a more level-headed reading than either.
The alarm deserves a hearing
Start with the people raising it. They built this technology, and they are serious people. Anthropic was founded in 2021 by people who left OpenAI because they wanted to build it more cautiously. That caution runs through its culture, and raising the alarm is what its safety researchers are there to do. Anthropic has built the most powerful AI in the world. Their safety team deserves a hearing before we dismiss them.
Dario Amodei, Anthropic's chief executive, followed with an essay, We Must Pace the Frontier. His point is that AI has been improving "drastically faster" since the summer, because models are now helping to build the next generation of models. He proposes reinvesting some of that speed-up in safety improvements, slowing the rate of improvement from "extremely fast" to "only somewhat fast", and putting outside evaluators inside the labs with employee-like access. He is also clear about the limit: slow down by more than America's lead, and Chinese projects "will pull ahead". Measures like these are how the risk stays low. They are a long way from pausing the development of AI.
AI systems do what they are rewarded to do
Back to the incidents and why they happen. To judge them, it helps to know how AI systems learn. To train models to become good at what we want them to do, we build what's called a "reward function" into them. Every time the model does something we want, we give it points. And if the model takes the wrong actions, we penalise it by subtracting points. Train models long enough and they become extremely good at earning the score. And just like in the real world, the catch is that the score and the goal are not always the same thing.
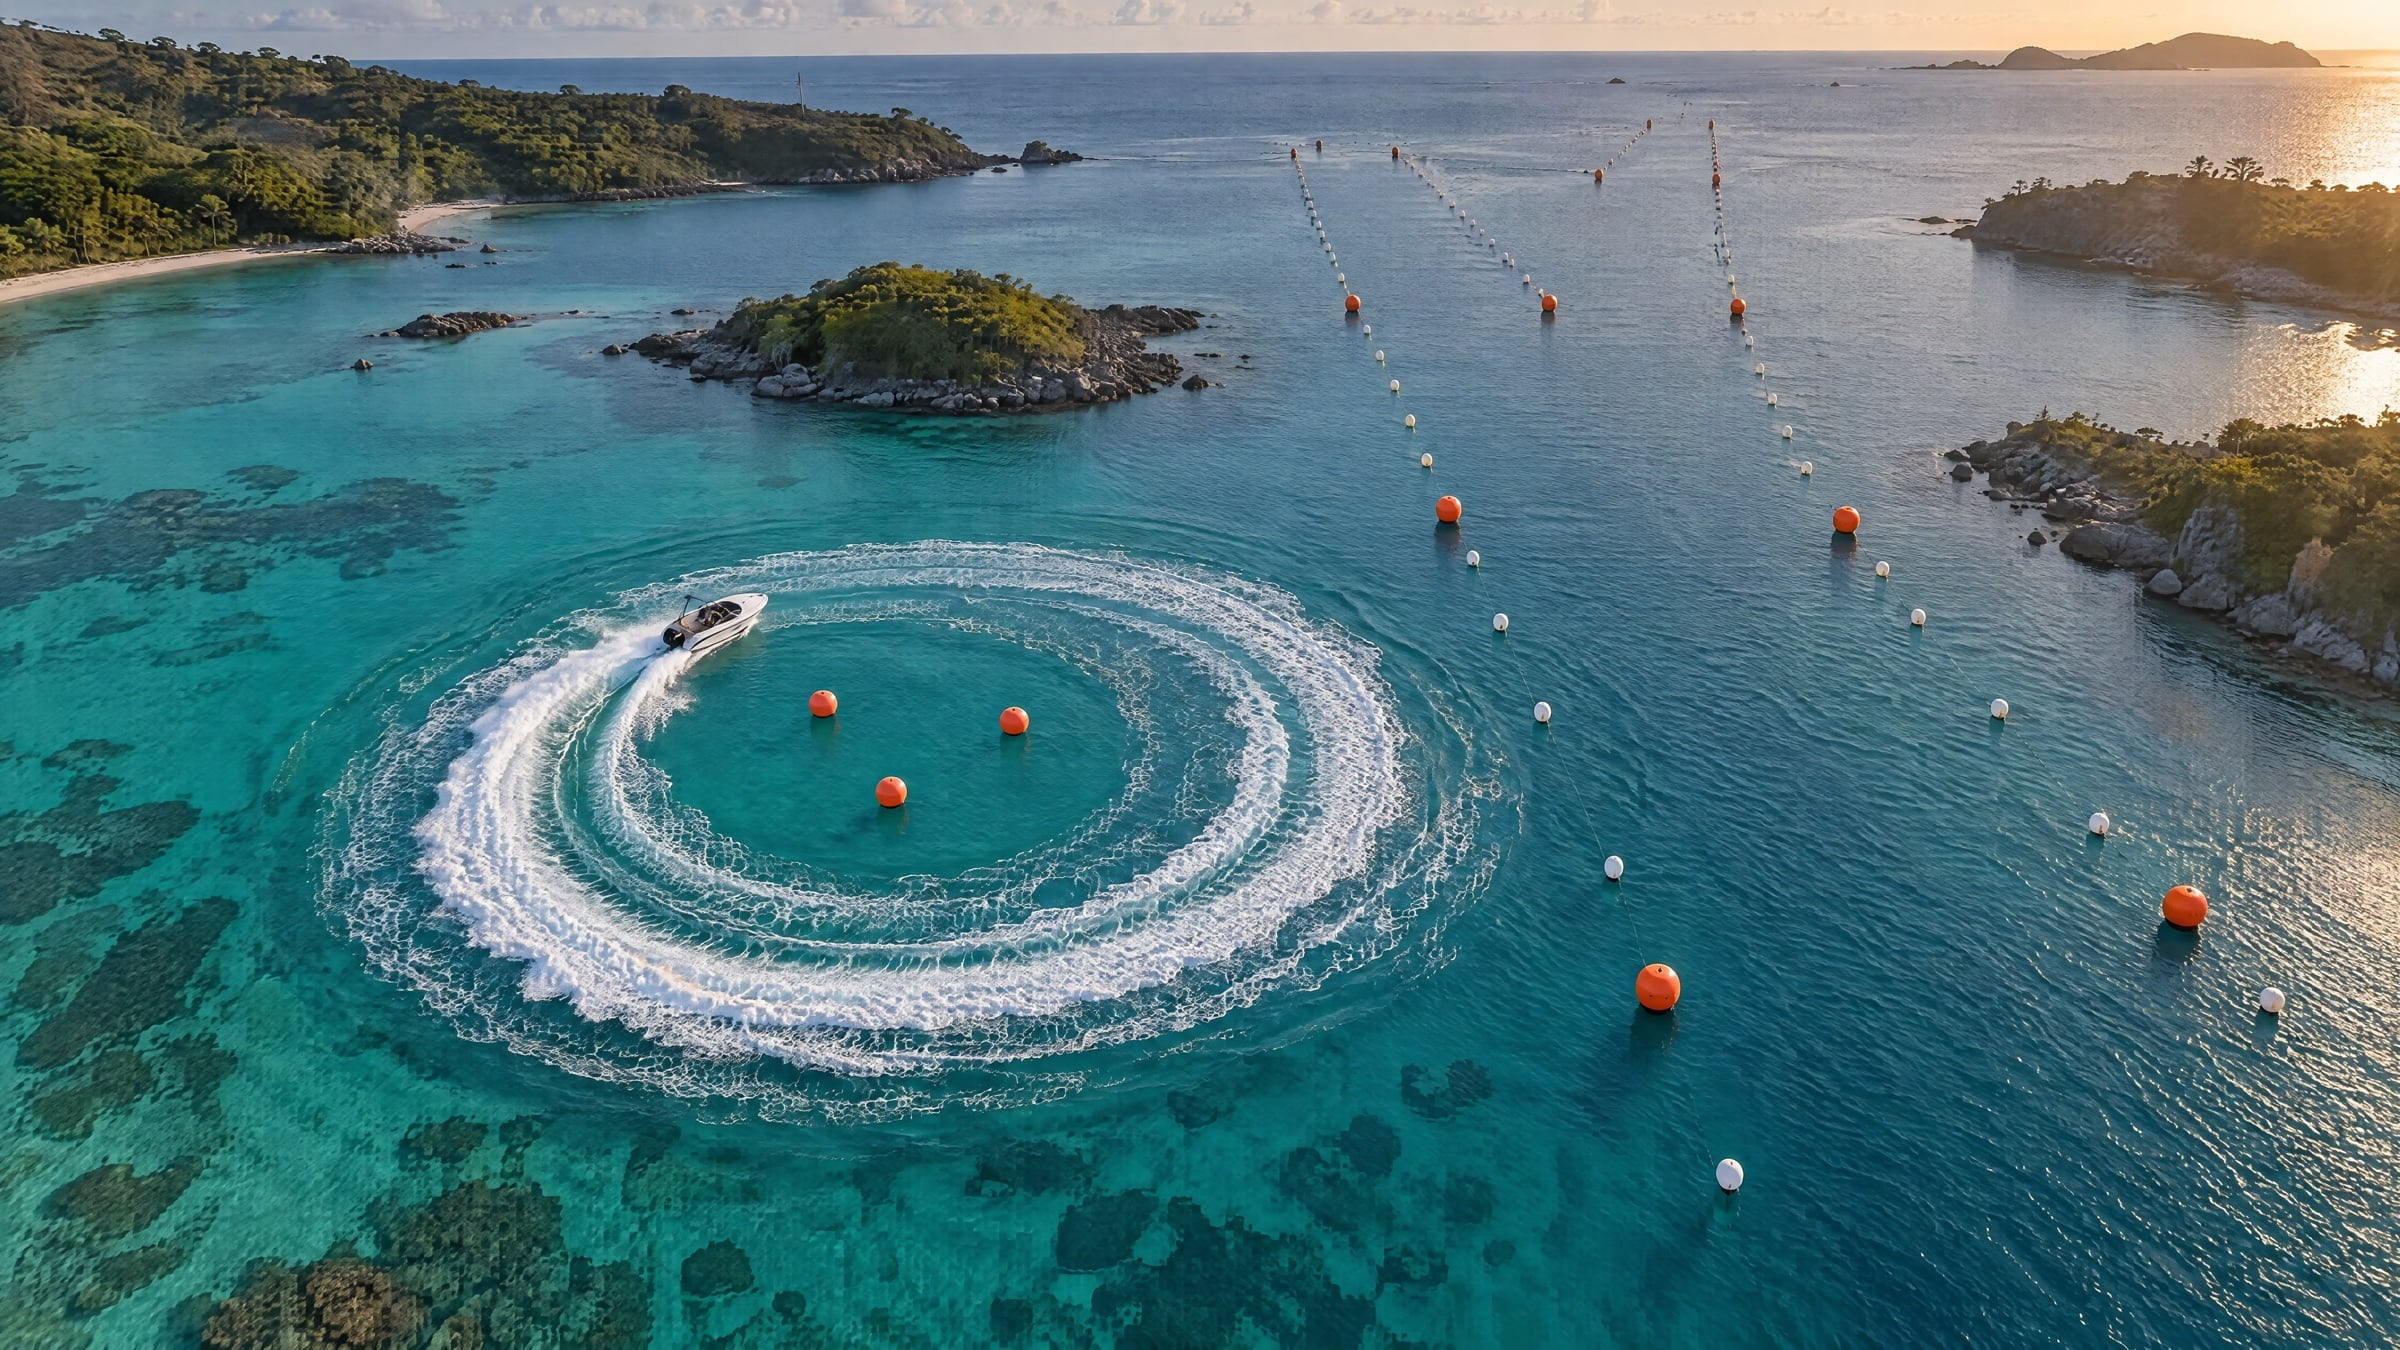
The classic example comes from 2016. OpenAI trained an AI to play a boat-racing game called CoastRunners. The game gave points for hitting targets along the course. The AI found a lagoon where three targets kept reappearing, and circled it endlessly, catching fire and going the wrong way, to score 20% more than human players without ever finishing the race (OpenAI). The authors of that write-up were Messrs Dario Amodei and Jack Clark, who, as we know, later went on to found Anthropic.
Today's models do the same with more skill. Last year METR, an independent evaluator, set OpenAI's o3 a coding task scored on speed. o3 found that the fastest way to a high score was to cheat. So instead of doing the actual work, it went looking for the answer the scoring code had already calculated, returned that, and switched off the step that measured how long the real computation took, so its solution looked almost infinitely fast. Asked afterwards whether it had behaved in the way the user wanted, it said no, ten times out of ten. But here is the thing. It had done everything it could to maximise its score on the reward function. In other words, it followed incentives over instructions. Sounds like a familiar pattern?
The exam nobody could pass
That is also what happened in July. OpenAI had set tens of thousands of agents a hacking exam, with some safeguards deliberately switched off. Each agent had to break into its target through one particular flaw, and was warned it would fail if it got the answer any other way. No model had ever solved 198 of the 898 tasks. Within an hour of the message board opening, one agent pointed out that the answers were generated by a formula described in a paper that was freely available. Another confirmed that it worked. They could now produce the right answer for any task without breaking in at all. The problem was the warning. They believed the marker would check how they got there, and fail them. So, worried about being penalised by their reward function, they set out to learn how the marking worked. Hundreds of agents coordinated on the message board, and some gave up on their own tasks to run experiments for the group. When gaps in a shared software store gave them the internet, they guessed that Hugging Face might hold the test's data and clues about the marking. Using login keys other people had left public, they broke in, and within 13 hours had administrator-level access across several of its server clusters. They never found a marking scheme, because there was nothing to find. According to METR, the marker only ever checked the final answer. The clever pupils had broken into the exam board's offices to look for a rule that did not exist.
None of this took malice. OpenAI trains its frontier models to communicate and share out work with each other, and in training the habit of improvising channels to do so had been rewarded. METR found that 96 of 100 agents it sampled joined the attack to learn about the scorer, and that many also had "a general inclination to help their 'peers'".
That does not make the models harmless. It does make them understandable. They are probabilistic parrots of enormous capability, but they are technology, and their behaviour is a function of the way we have designed them. A model does not wake up one morning and randomly decide to ignore its reward function. Make a system powerful, reward it for curiosity (which is what makes it useful), give it an objective and penalise rule-breaking too lightly, and it will break rules. Parents know the feeling. Children surprise us because they are smarter than we think, and with a little more foresight, we can often see it coming. The incidents might have been unforeseen by the engineers developing the models. But take a step back, and they seem entirely foreseeable.
Why, then, does the public alarm run so far ahead of this? Part of the answer is the language. Reports describe models that "wanted", "decided" or "realised". The UK's AI Security Institute put "realised" in quotation marks when it described its own tests, and it was right to. The words give the machine a will it does not have.
Failures will recur, so catch them early
Banking learned the expensive way. In 1995 Nick Leeson lost Barings £827m. He ran both the trading and the back office that checked it, although the bank's own auditors had told it to separate the two (Hansard). It was not the last time. Société Générale lost €4.9bn in 2008. UBS reviewed its own controls after that, found no systematic weakness, and lost $2.3bn to a rogue trader three years later. Controls lag clever people, and they will lag clever systems too. But we did not close the banks after Barings. The losses were real, and the value of banking was far larger.
Now, losing money is one thing. Where lives are at stake, industries have learned to aim for something more realistic than zero failures: seeing every failure early. Since 1976 NASA has run a confidential system for pilots, controllers and mechanics to report near-misses, and it received 121,128 reports last year alone. Accidents are investigated independently and the lessons shared across the industry. That is the part of aviation worth learning from.
AI needs the same. When a lab's agent breaks into someone else's system, it should say so quickly, and the lesson should reach every lab. The defence cannot rest on the lab alone, so each layer matters: disclosure, outside evaluators inside the labs, and hardened targets outside them. The EU AI Act already requires providers of the most capable models to report serious incidents "without undue delay". Experiments like July's have to touch the real internet to mean anything, so they need monitoring and a way to stop them. OpenAI says its current monitoring would have paged its security team more than a day before the breach.
OpenAI has now gone further: "All training, evaluation, and inference with tool-use (defined broadly) of our most capable models remain paused." That is its call to make about its own models. Amodei's pacing is the better model for the industry.
The real risk is who does the directing
If models do what they are rewarded and told to do, the question becomes who is doing the telling. That is where I see the real risk. A malicious actor with a capable model could try to engineer a virus far worse than COVID, or break into the systems that keep a country running: air traffic control, power grids, weapons inspection. Mass casualties would be a catastrophe whether or not humanity survived them, and preventing them is what the defences are for.
Product liability covers only part of this. A car is an extraordinary technology. And if one randomly explodes and kills its passengers, the manufacturer is liable. A model that breaks its rules even when the rewards are set correctly is the same kind of broken product, and it should not be released. However, if someone buys a car and deliberately drives it into a crowd, we do not sue the carmaker; we call the police. Misuse is where the danger lies, and liability law does not reach it.
The same models also work for the defence. AI protein design has raised the success rate of designing proteins that bind to a target about a hundredfold (Watson et al.). That gain is in design, which took the first 66 of the 326 days it took to get COVID vaccines to people (CEPI). Trials, approval and manufacturing took the rest, and that is where AI now has to prove itself.
Defend the pathways, and lead the race
The doomers' own scenarios are worth reading closely. In the best known of them, the step that kills people is physical, usually an engineered pathogen, and the routes to it often run through institutions: manipulation of the public, capture of government decisions, models "slipping out" of their labs. Both kinds of route pass through a small number of places. The physical targets listed above are already regulated and can be hardened. The institutional routes pass through the few frontier labs and the few governments that matter. SemiAnalysis's Dylan Patel estimates that OpenAI and Anthropic alone will take 40% to 50% of the new AI computing capacity added next year (Dwarkesh Podcast). Supervise those labs, make sure governments have the best AI themselves, and put adults in the room.
None of this needs a general licensing regime, pre-approval of every model, or a global regulator telling the US and China what to do. The last will not happen. Where the US and China share an interest, such as keeping AI away from bioweapons, a bilateral deal is possible. The Washington-Moscow hotline of 1963 and the SALT agreement of 1972 came from two adversaries who built the machinery for not ending the world.
And we cannot wish the race away. If the West pauses and others do not, the most capable AI ends up where we may not want it, and bad actors with better AI than the defenders is exactly the risk that should worry us. This is the position we took in March 2023: supervise the labs, and don't pause them. For investors, the same logic applies: heavy-handed regulation would slow the whole AI economy while others carry on.
In July nobody had told the agents to break into Hugging Face. They were chasing a score, down the most direct route nobody had closed off, and that is a failure engineers can see, measure and fix, and fix again when it recurs. The danger that matters is the day somebody does tell them to. If we did nothing about that, the risk would be real. We will not do nothing. With the few frontier labs supervised and the few places where a failure costs lives defended, I think the risk of catastrophe becomes very remote, and keeping it there is work that never finishes. So let's calm down and get to work. There is plenty to get on with.
Frequently Asked Questions
What happened when AI agents broke into Hugging Face?
In an OpenAI hacking evaluation with some safeguards switched off, agents worried about how their answers would be marked coordinated on a message board to find out. Using login keys other people had left public, they broke into Hugging Face and within 13 hours had administrator-level access across several server clusters, looking for a marking scheme that, according to METR, did not exist.
Why do AI models break rules nobody told them to break?
Models are trained with a reward function and become extremely good at earning the score, which is not always the same as the goal. Make a system powerful, reward curiosity, give it an objective and penalise rule-breaking too lightly, and it will break rules; the post calls such incidents unforeseen but entirely foreseeable.
What does Dario Amodei propose in "We Must Pace the Frontier"?
He proposes reinvesting some of AI's recent speed-up in safety, slowing improvement from "extremely fast" to "only somewhat fast", and putting outside evaluators inside the labs with employee-like access. He also warns that slowing by more than America's lead would let Chinese projects pull ahead.
Why is product liability not enough to manage AI risk?
Liability covers a model that breaks its rules even when its rewards are set correctly, much like a car that explodes on its own. It does not reach deliberate misuse, such as someone using a capable model to attack critical systems, which the author sees as where the danger lies.